
Key Takeaways
- Network resilience combines availability, security, visibility, backup options, and recovery planning.
- Every business should identify its critical applications, locations, devices, and single points of failure.
- Backup connectivity works best when it uses a different provider or technology from the primary connection, where practical.
- Identity-based access, segmentation, and multi-factor authentication help reduce risk across offices and remote environments.
- Testing failover and recovery processes is as important as deploying them.
Table Of Contents
- Why Network Resilience Matters
- Map The Current Network Environment
- Prioritize Critical Applications And Traffic
- Build Redundancy Into Key Connections
- Protect Office, Cloud, And Remote Access
- Improve Monitoring And Visibility
- Create A Practical Recovery Plan
- Follow A Step-By-Step Plan
- Avoid Common Mistakes
- Frequently Asked Questions
- Conclusion
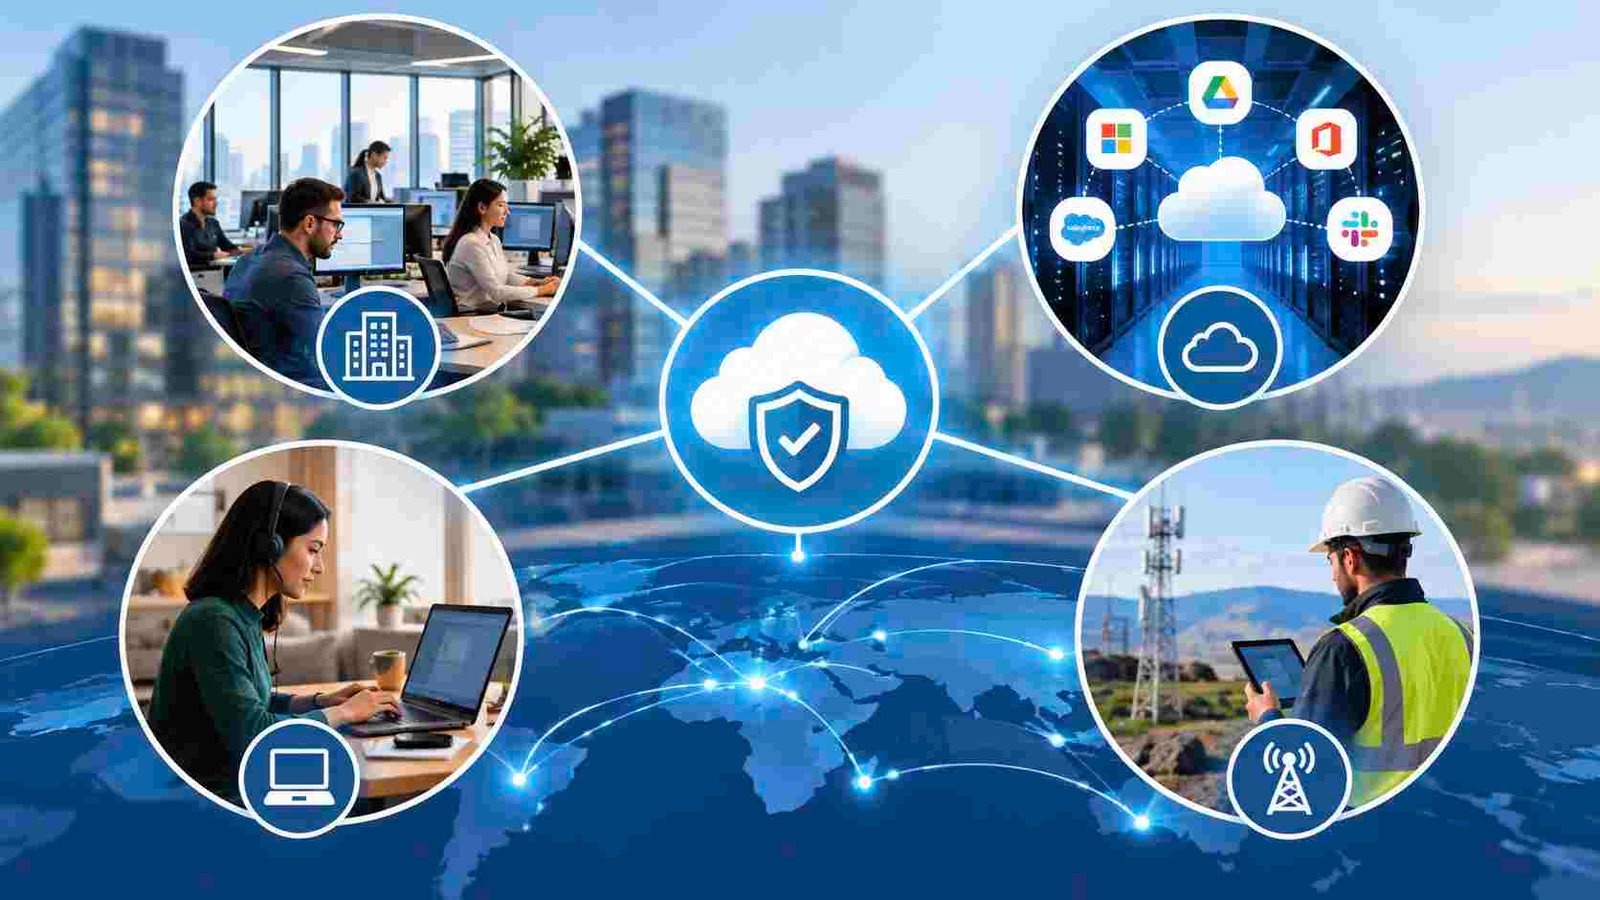
Modern organizations depend on reliable connectivity for cloud software, payment processing, collaboration tools, hosted phone systems, security cameras, and remote work. Well-planned network connectivity solutions can help create a foundation for continuity, but resilience also requires thoughtful design, security controls, monitoring, and tested recovery procedures.
A resilient network is not simply a fast network. It is a network designed to continue supporting priority work when a circuit, device, power source, or access method fails. The right level of investment depends on the operational cost of downtime at each location.
Why Network Resilience Matters
A short disruption can prevent employees from processing orders, responding to customers, accessing files, joining meetings, or accepting digital payments. Consider a retail site with one internet circuit. If that circuit fails, the point-of-sale system, inventory platform, and card terminals may all be affected at once. Resilience reduces this exposure by preparing alternate paths and clear response steps before an outage occurs.
Speed measures capacity. Availability measures whether a service is reachable. Security protects systems and information. Resilience brings these disciplines together so priority services can continue or recover quickly when conditions change.
Map The Current Network Environment
A business cannot reliably protect or improve connections it has not documented. Start with an inventory of every office, branch, warehouse, remote site, and home-based work group. Record providers, circuit types, contract details, equipment, wireless networks, cloud applications, and vendor connections.
Create a simple network diagram that shows routers, firewalls, switches, wireless access points, servers, printers, cameras, and major cloud services. Include data flows between users, applications, locations, customers, and third parties. This document makes it easier to spot dependencies, plan maintenance, and identify single points of failure.
Prioritize Critical Applications And Traffic
Not all traffic should receive the same priority during a disruption. Classify applications into three practical groups:
- Mission-critical: payment systems, order processing, production tools, emergency communications, and industry-specific operational platforms.
- Important: email, collaboration platforms, standard cloud storage, and internal business systems.
- Routine: guest browsing, large downloads, software updates, and non-business streaming.
Measure performance during busy periods, not only through advertised internet speeds. Latency is a delay, jitter is a variation in delay, and packet loss occurs when data does not reach its destination. These conditions can affect voice, video, cloud applications, and remote desktop sessions even when a connection appears to have enough bandwidth.
Build Redundancy Into Key Connections
Redundancy means having another workable path when the primary one fails. A backup does not have to be an identical second fiber circuit. Depending on location and business needs, the alternate option may be wired broadband, fixed wireless, cellular service, satellite connectivity, or a second carrier.
When possible, avoid putting both primary and backup services on the same provider or physical route. Automatic failover is usually appropriate for locations that cannot wait for a technician to intervene. Manual failover may be sufficient for a lower-risk office if documented procedures and responsible staff are available. Network equipment also needs backup power, such as an uninterruptible power supply, and critical sites may require generator support.
Protect Office, Cloud, And Remote Access
Distributed work makes identity and device security central to network design. Joint cybersecurity guidance from CISA and its partners emphasizes stronger visibility and protections for remote computing environments, rather than relying only on a traditional network perimeter.
- Require multi-factor authentication for administrators, remote access, and important cloud accounts.
- Apply least-privilege access so users receive only the permissions needed for their responsibilities.
- Separate employee devices, guest Wi-Fi, cameras, operational technology, and sensitive systems.
- Keep firmware, endpoints, network devices, and cloud settings current.
- Review contractor, vendor, and former employee access on a defined schedule.
Improve Monitoring And Visibility
Monitoring helps teams identify trouble before it becomes a widespread user complaint. Track uptime, bandwidth use, latency, packet loss, device health, failed links, unusual traffic, and repeated login attempts. Centralized dashboards are especially useful when multiple locations share a small IT team.
Each month, review whether critical links were stable, whether capacity approached limits, whether alerts were handled promptly, and whether documentation still reflects the real environment. Retain logs long enough to support troubleshooting and security investigations.
Create A Practical Recovery Plan
A recovery plan turns a technical failure into a manageable business event. Define the recovery time objective, which is how long a service can remain unavailable, and the recovery point objective, which is how much recent data the organization can afford to lose.
- Name the people authorized to make recovery decisions.
- Specify which applications, locations, and communications services return first.
- Document provider contacts, escalation paths, credentials, and equipment details.
- Keep diagrams and instructions available offline.
- Establish an alternate communication method if email or phones are unavailable.
- Run tabletop exercises and live failover tests.
Follow A Step-By-Step Plan
- Assess: Inventory assets, users, applications, connections, and risks.
- Prioritize: Rank systems by business value and acceptable downtime.
- Design: Plan segmentation, access controls, backup paths, monitoring, and recovery steps.
- Deploy: Start with the highest-risk sites or services and make changes in stages.
- Test: Simulate link failures, device loss, compromised accounts, and power interruptions.
- Improve: Update the design as locations, applications, staff, and risks evolve.
Avoid Common Mistakes
- Relying on one provider, device, or physical connection path.
- Adding bandwidth without addressing weak Wi-Fi coverage or outdated equipment.
- Installing backup connectivity but never testing failover.
- Operating a flat network where one compromised device can reach unrelated systems.
- Leaving inactive accounts, unused remote services, or vendor access enabled.
- Storing recovery instructions only on systems that may be unavailable during an outage.
Frequently Asked Questions
What Makes A Business Network Resilient?
A resilient network has reliable primary connectivity, appropriate backup options, secure access controls, segmentation, monitoring, documented recovery procedures, and routine testing.
Does Every Business Need Two Internet Providers?
Not necessarily. The decision should reflect the cost of downtime, available technologies, and the services that must remain online. A cellular or fixed wireless backup may be appropriate for some lower-risk sites.
What Does Zero Trust Mean In Simple Terms?
Zero trust treats access as something that should be verified based on identity, device, context, and policy rather than assumed because a user is inside the office network. NIST provides practical examples for implementing a zero-trust architecture across on-site, cloud, and remote environments.
Conclusion
Network resilience is an ongoing business practice, not a one-time equipment purchase. Begin with a clear map of the environment, focus protection on critical services, add realistic backup options, secure every access path, and test the results. Preparation helps employees remain productive, supports customer service, and reduces confusion when a disruption occurs.